STM32 Edge NPU Vision & MLOps Pipeline
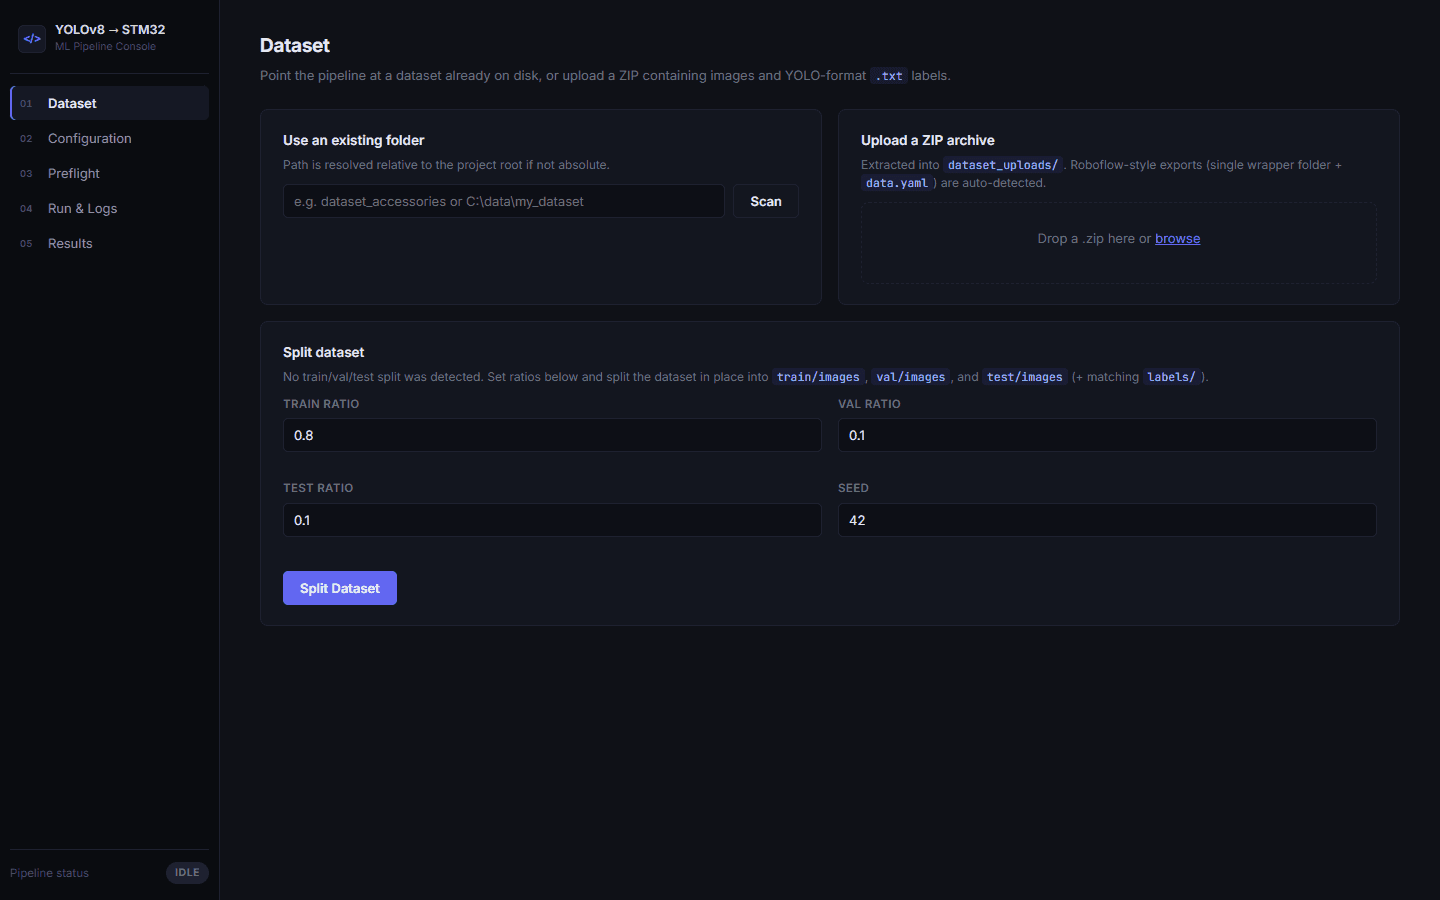
overview.
Built to run real-time physical board-state perception on the STM32MP257F-DK's 1.35 TOPS Neural Processing Unit under OpenSTLinux rather than a desktop GPU. A classical OpenCV stage detects the board via Canny edges and adaptive thresholding, applies a 320x320 homography warp with EMA corner stabilization, and feeds a custom-trained YOLOv8n detector backed by per-cell temporal voting. A unified inference wrapper runs PyTorch (.pt), ONNX Runtime with VSINPUExecutionProvider (.onnx), TFLite with libvx_delegate INT8 (.tflite), and ST Neural Binary Graph (.nb) models. Around the detector sits an automated, resumable 11-stage MLOps web dashboard covering dataset validation, augmentation, training, evaluation, ONNX opset-12 export, INT8 post-training quantization, ST Edge AI Developer Cloud compilation, SSH deployment, on-board CMA/latency verification, and report generation.
key features.
- 0.998 precision, 1.000 recall, 0.995 mAP@0.5, and 100% cell-level accuracy across 449 held-out cells
- INT8 post-training quantization and NPU compilation shrinking weights from 6.22 MB (FP32) to 3.10 MB (TFLite INT8) and 2.68 MB (.nb NPU binary)
- Resumable 11-stage MLOps web dashboard automating dataset scan, training, PTQ calibration, ST Edge AI Cloud compilation, and SSH board deployment
screenshots.
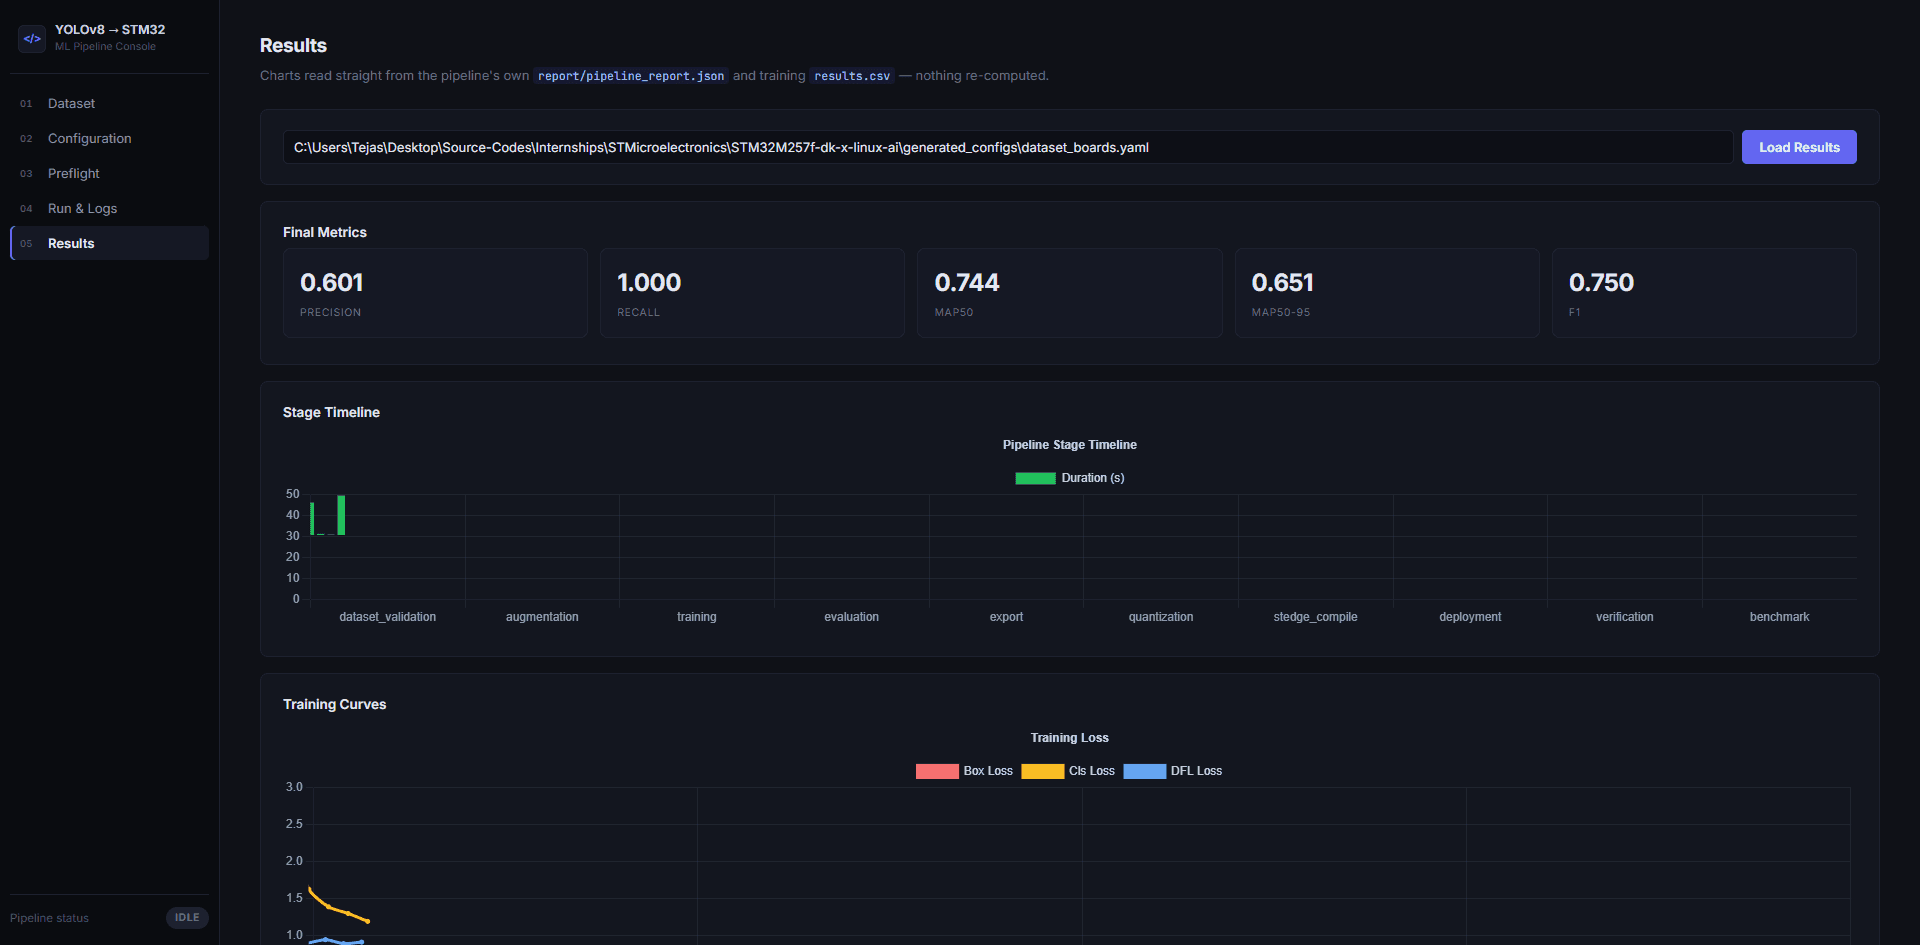
11-stage MLOps pipeline evaluation results and backend latency comparison
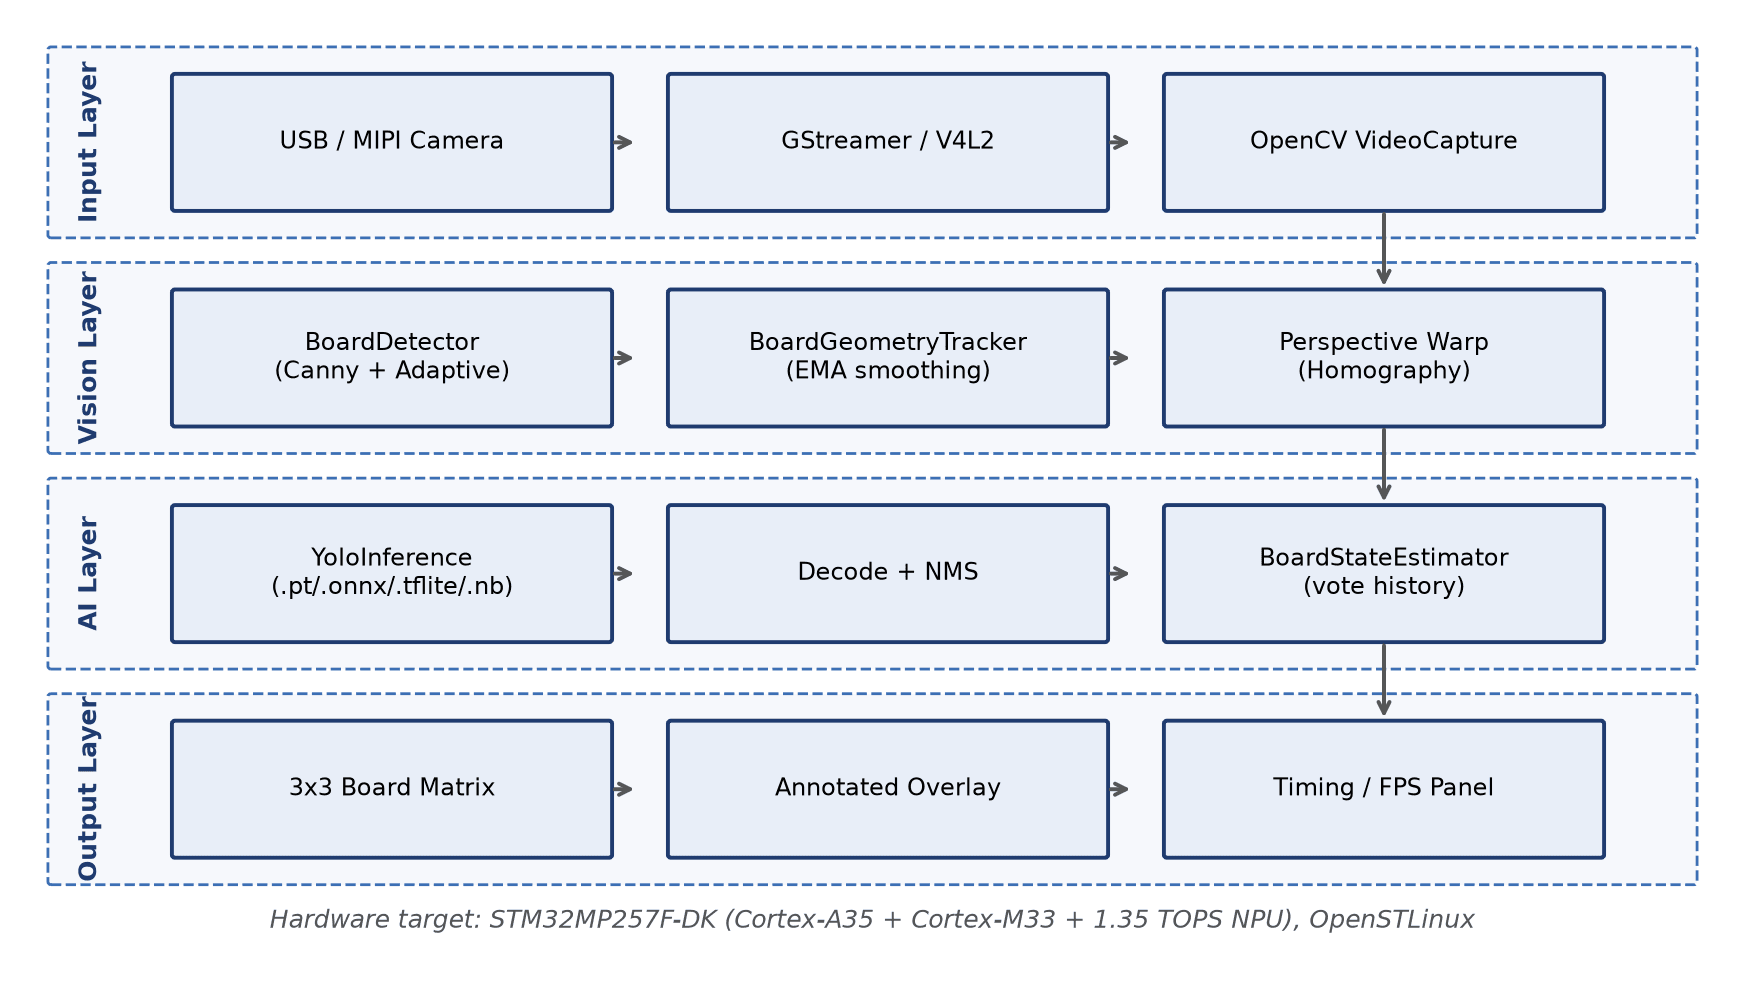
End-to-end architecture from camera homography warp to STM32MP257 NPU inference